Snorkel AI on Sept. 22 announced a $350 million Series E at a $3.5 billion valuation, a sharp re-rating for a company better known for data-labeling software than for model-building headlines. In Snorkel’s announcement, the company said its data-as-a-service business, launched nearly a year ago, has grown more than 18x and crossed a $375 million annualized revenue run rate. Reuters, in a report carried by MarketScreener, described the run rate as above $350 million. The immediate significance is not a new foundation model. It is that investors are assigning infrastructure-style value to a supplier of difficult training and evaluation data.
That makes the real question more useful than the financing itself: has “Data 2.0” become a durable layer of the AI stack, or is this mostly a high-growth extension of frontier-model spending? For buyers and investors, the answer will turn less on slogans like agentic data than on harder proof: independent model lift, clean provenance, sustainable expert economics, customer concentration, and the difference between annualized run rate and audited revenue.
What Snorkel is actually selling
Snorkel, founded in 2019 by researchers who spun out of Stanford’s AI lab, began by selling software for data labeling and development. Reuters reported that it has since shifted toward delivering finished datasets and reinforcement-learning environments directly to customers. The company now describes its platform as an agentic data-development system that combines human experts with thousands of specialized AI models and agents.
That distinction matters. In Snorkel’s framing, humans are not just checking boxes at the end of a workflow. Specialists design scenarios, tasks, and grading rubrics. Automated systems handle parts of generation and quality assurance. The output is then sold as a reusable data product rather than billed as ordinary labor hours. Snorkel says it works with frontier AI labs, hyperscalers, vertical AI companies, enterprises, and U.S. government agencies; Reuters reported a network of tens of thousands of specialists across coding, law, medicine, and other fields, with coding data among the biggest demand centers.
This is a different business from the first wave of AI data work. “Data 1.0” emphasized volume: large pools of raw examples and relatively simple labels. The current bottleneck is the last mile. As models improve, a valuable data point may require an expert to spend days building a realistic task, checking whether the model found a shortcut, and confirming that the resulting score actually measures the intended capability. In practice, the scarce asset is not just more data. It is curriculum design, evaluation design, and failure-mode discovery.
Why the category looks real — and why the proof burden is higher
There is enough market context to take the category seriously. Reuters reported that Snorkel’s previous financing valued the company at $1.3 billion after a $100 million round in May 2025, so the new valuation is nearly triple the prior mark in roughly sixteen months. Reuters also noted that Meta’s $14.3 billion purchase of a 49% stake in Scale AI in June 2025 helped reset expectations for companies supplying training data, while competitors including Mercor and Surge AI have attracted capital as well. The market is clearly treating difficult data production and evaluation as more strategic than outsourced annotation.
But the financing does not settle the infrastructure case. Snorkel’s $375 million figure is a company-reported annualized run rate, not audited GAAP revenue. Reuters’ “above $350 million” description points to the same momentum, but not to a fully comparable public-company revenue number. Nor does rapid growth prove that demand is broad, sticky, or economical. A supplier can post fast run-rate expansion if a small number of large labs are buying aggressively, even if contracts are short, fulfillment is labor-heavy, or margins are thin.
There is also a causality problem. Better model performance can come from architecture changes, more compute, inference-time techniques, or customer-specific engineering. Data may be the differentiator, but it is not automatically the differentiator. To deserve infrastructure multiples over time, a vendor has to show that its datasets or evaluation environments create measurable gains that survive on held-out tasks and matter in deployment, not just in a vendor-managed benchmark.
What a buyer should demand before paying for “agentic data”
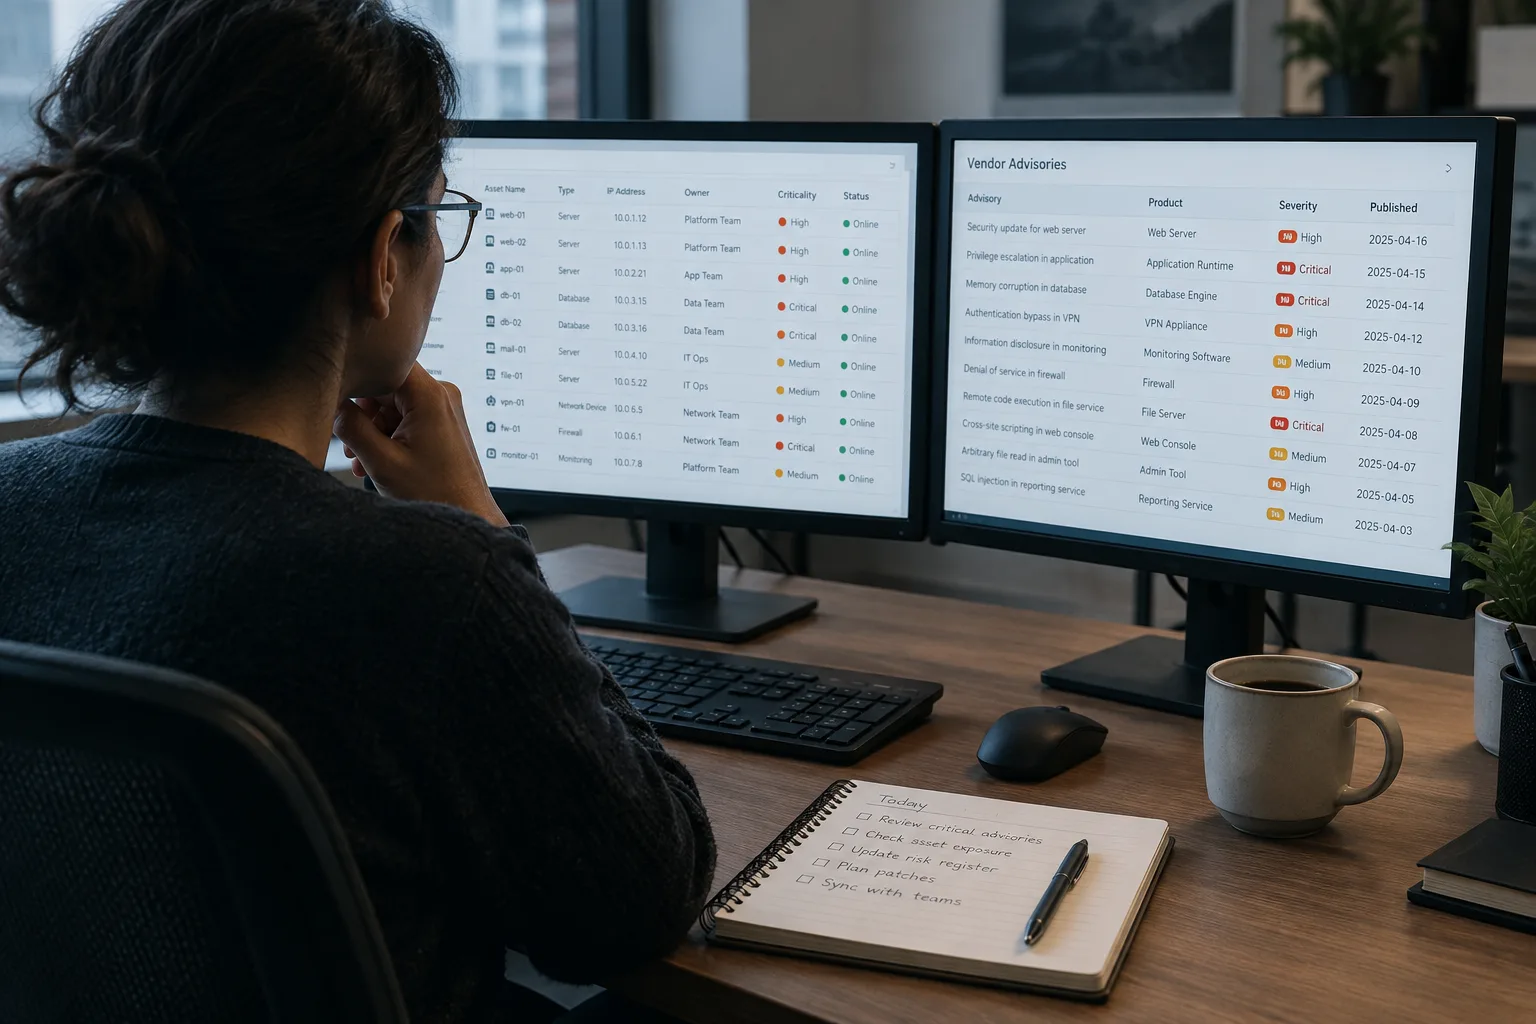
For procurement teams, the right question is simple: what did this engagement improve, and how do we know? In a bank, hospital system, cloud platform, or government program, a data vendor should be able to produce a package that goes beyond a polished dashboard.
A practical buyer checklist includes:
- a precise task specification, target failure mode, and success metric
- a provenance and rights record showing where source material came from and what can be reused
- contamination controls, especially if synthetic or simulated data touches evaluation work
- independent scoring or customer-auditable scoring, not only vendor grading
- human-review rates, rework rates, and examples of failure cases
- a before-and-after benchmark tied to a business metric such as accuracy, robustness, speed to deployment, or reduced manual review
- expected expert time per validated data point or per evaluation environment
Those requests are not procurement bureaucracy. They are the difference between buying a durable asset and outsourcing busywork. If the claimed lift disappears on held-out tasks, if the benchmark can be gamed, or if the resulting environment leaks proprietary information, the customer has not bought infrastructure. It has bought a temporary service engagement with unclear reuse value.
Investors should separate category excitement from company economics
Snorkel says it expects to reach profitability in 2026 and plans to use the new capital to expand research and engineering, enterprise and government operations, model evaluations, and additional data modalities. That is plausible for a company trying to industrialize a research-heavy workflow. It is not, by itself, proof that the model already scales cleanly.
The missing metrics are the ones that will determine whether this is a durable business or just a well-funded rush: customer concentration, contract duration, renewal rates, gross margin by product, compute intensity, cost per validated data point, and the share of work done by humans versus automated systems. In this category, top-line velocity can coexist with expensive experts, heavy rework, and high delivery risk.
The strongest long-term case for Snorkel is that advanced AI is creating a new class of knowledge work around curriculum design, environment engineering, evaluation, and adversarial testing. If that is right, human expertise may become more valuable, not less, as automation handles larger parts of the pipeline. The weaker case is that today’s budgets are still dominated by a small number of frontier-model buyers, making the category more cyclical and concentrated than the valuation suggests.
Snorkel’s round is a strong signal that the hardest part of AI development is moving from data collection to data design. What it does not yet prove is which vendors can turn that shift into audited revenue, repeatable model lift, and defensible economics. Until that proof is easier to see, the most valuable output in “Data 2.0” may not be more examples. It may be trust.
 By
 By
 By

 By


 By