
Meta on Oct. 12 introduced Muse Wonder and Muse Wonder Full, its first frontier-model release from the company’s Superintelligence Lab after a 14-month AI overhaul. Wonder is available immediately through the Meta Model API and Muse Code; Wonder Full is available immediately to Muse Code subscribers. That makes this more than a benchmark announcement. It is a same-day model, product and distribution move aimed at turning frontier AI into an agent people and businesses might actually use.
The question buyers need answered is straightforward: does Muse Wonder change the economics of dependable AI agents, or does it mostly show that Meta has reached the frontier conversation while the harder memory, permissions and accountability problems still sit outside the model? The early answer is mixed. Meta has made the commercial proposition more concrete, especially with posted API pricing and a clear product funnel. But the launch also sharpens the cost and control issues that usually decide whether an agent survives beyond a pilot.
A frontier release with a built-in funnel
According to Meta’s announcement, Wonder is the developer-facing model: it is available through the API and Muse Code now, and Meta says it will soon power more Muse experiences and future artifact-generation workflows. Wonder Full is more restricted. It is available to Muse Code subscribers, not through the API.
That access split matters. Meta is not simply releasing a top-tier model and letting the market sort out the rest. It is tying model capability to its own coding surface, its developer platform and, soon, its consumer Muse experience. For Meta, that is a sensible way to turn a model launch into recurring usage. For developers and enterprise buyers, it creates a practical distinction between what can be procured as infrastructure and what remains part of Meta’s own subscription product.
The company is clearly trying to close a perceived gap with OpenAI and Anthropic. TechCrunch reported that Meta’s own testing places Wonder and Wonder Full near Fable 5.1 and GPT-6 Astra on selected benchmarks. That is enough to put the models in the frontier tier discussion. It is not enough, on its own, to settle how well they handle messy enterprise work, where reliability depends on permissions, retrieval, logging and recovery as much as raw reasoning.
Why memory is the real product claim
Meta’s more distinctive pitch is continuity. In its research materials, the company says Active Memory carries relevant details across conversations, while Active Focus lets the model keep working on a task, try alternatives, recover from errors, ask for clarification and check in before important actions. The examples span personal context, unfamiliar tasks, software building, and work across browser and app environments.
Those are not cosmetic features. They address the reason many current agents feel brittle in daily work: they forget context, drop intent, or require the user to restate the job every few turns. If Wonder can remember a user’s preferences, project state or prior instructions without constant re-prompting, it could reduce repetitive supervision. If Active Focus really improves recovery after a failed tool call or a changed environment, it could make agents less likely to stall the first time a workflow goes off script.
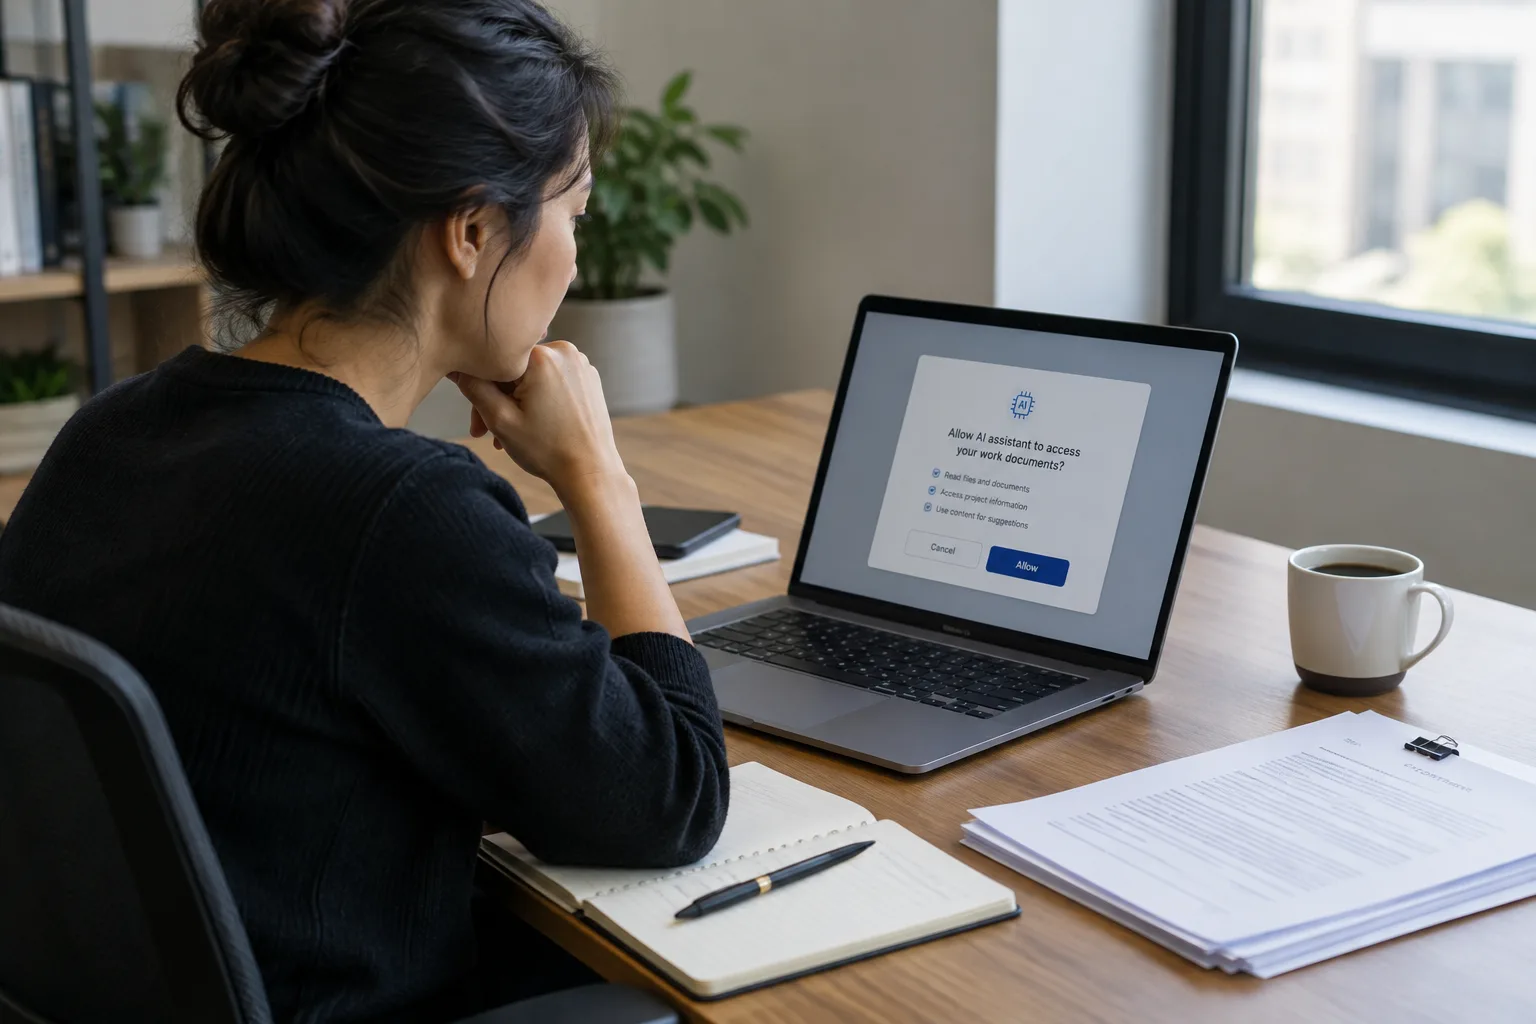
But the same capabilities expand the governance surface. A system that remembers useful context must also decide what not to remember, what to update, what to ignore and what to delete. A system that keeps pursuing a goal can also keep pursuing a mistaken goal. For businesses, that turns model quality into record-keeping and policy questions: what is stored, where it lives, whether it is scoped to a user or workspace, how stale instructions are corrected, and whether retrieval can be inspected after the fact.
That is especially important because Meta is positioning Wonder for tasks involving leases, insurance claims, finance and health information. Those are exactly the categories where a remembered preference can save time, and where a carried-forward error can create real risk.
The token price is only the first line of the bill
TechCrunch reported API pricing of $4 per million input tokens and $20 per million output tokens for Wonder. That is useful because it gives developers a concrete reference point for agentic workloads. But it is only the starting number.
Long-running agents rarely stop at token usage. They add browser execution, tool calls, storage, monitoring, retries, evaluation, human review and security controls. In practice, Active Focus may improve success rates while also increasing the number of intermediate steps an agent takes on the user’s behalf. If the model tries alternatives, recovers from errors and checks back before consequential actions, that can produce better outcomes—but it also adds events to log, actions to approve and runs to monitor.
Wonder Full’s subscriber-only distribution complicates pricing further. The headline capability in Meta’s new family is not yet a like-for-like API option for every buyer. A company deciding between model vendors is therefore not just comparing token prices; it is comparing access paths, support models and how much of the most capable experience stays inside the vendor’s own product.
The control plane may be where the value moves
This is why the most important consequence of the launch may sit outside the model itself. If memory and persistence make agents genuinely more useful, they also increase the value of the software around them: permission brokers, memory stores, audit logs, approval gates and rollback tools. Enterprises may want those controls to be model-agnostic, precisely because frontier capabilities move faster than governance policies do.
Meta says the models are aligned with its Superintelligence Scaling Framework, and it has said additional safety evaluations will be published later. What buyers do not yet have are some of the operational details that determine whether a persistent agent is manageable at scale: how memory is inspected and deleted, how long it is retained, when human confirmation is required, how tool permissions are scoped, and how a user stops or unwinds a bad action.
So the launch does two things at once. It strengthens Meta’s claim to be back in the frontier-model race, and it shifts attention to the less glamorous layer that will decide commercial adoption. If Wonder turns continuity into something developers can govern, Meta will have done more than match a benchmark table. If not, businesses may find that the real spending lands not on a smarter agent, but on the control systems needed to keep that agent trustworthy.
 By
 By
 By

 By



 By