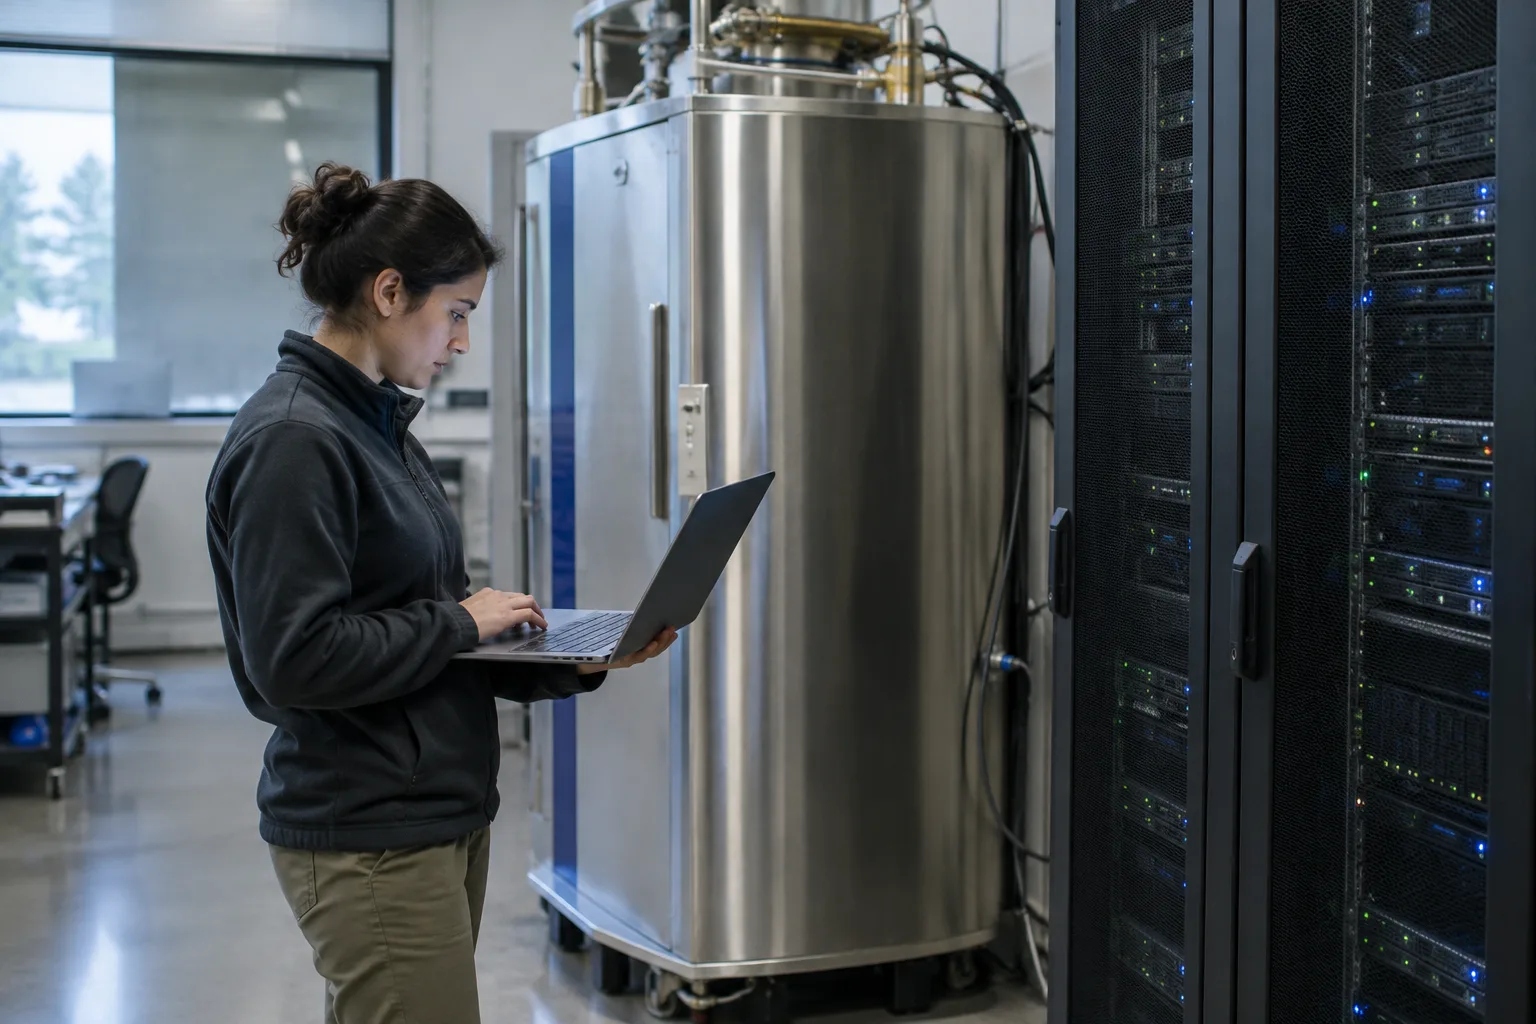
IBM has used its latest quantum announcement to shift the conversation from bigger chips to bigger systems. In IBM’s Nov. 11 announcement, the company said its planned Nighthawk r3 superconducting processor is designed to execute 10,000 quantum operations across 520 programmable qubits, with 2,034 physical qubits under the hood and 10 chip-to-chip interconnects it calls l-couplers. IBM also said it plans to link two r3 processors into a single 1,040-qubit system in 2027.
That matters because the real business question around quantum computing has changed. It is no longer just whether a vendor can announce a larger device. It is whether modular hardware, hybrid classical integration and credible workload results can make quantum experimentation faster, cheaper and more repeatable for paying users.
Why this is more than a qubit count
The headline numbers are useful, but only in context. Qubit count by itself is a weak proxy for economic value. Enterprises care about how many operations a machine can run accurately, how quickly it can collect samples, how much classical post-processing it needs, whether results are reproducible and what all of that costs in a shared cloud environment.
On that score, IBM is trying to improve two levers at once: depth and throughput. Quantum applications often require repeated sampling of circuit results, so a processor that can sustain deeper circuits while collecting enough samples quickly can shorten experiment cycles and reduce some of the surrounding classical-compute burden.
The best current reference point is not r3 but Nighthawk r2, which IBM made available in September. IBM says r2 supports more than 7,500 quantum operations on 120 programmable qubits and can deliver up to 100,000 samples per second. It also says clients and partners including E.ON, Algorithmiq and Q-CTRL have run more than 34 billion circuits on r2 and reported speedups of up to 19 times relative to earlier IBM quantum processors. Those figures do not prove commercial advantage, but they do show IBM has something more substantial than a lab demo as a starting point.
Modular links are the real test
The more important part of the r3 story is not the 520-qubit figure. It is the attempt to scale through links between modules rather than through one ever-larger monolithic chip.
That is what the 10 l-couplers are for. If they work as intended, IBM can add quantum capacity incrementally, connect processors inside a larger system and keep moving toward higher qubit counts without treating every generation as a single-chip engineering moonshot. The strategy also fits how enterprise infrastructure actually evolves: in modules, clusters and managed services rather than as one giant appliance.
But modular quantum hardware is only valuable if the links preserve enough quality to keep the whole system useful. Every interconnect adds more than wiring. It adds calibration overhead, control complexity, cryogenic demands and scheduling constraints. It also widens the system-level error budget.
IBM has shown an earlier version of that approach can work in limited form. The company says it connected two r1 processors using four l-couplers and measured quantum-state-transfer fidelity of up to 99.3%, against a 99.9% target. That is an encouraging datapoint, not a solved problem. It does not establish that two r3 processors will hit the same or better fidelity once the scale, control burden and cooling requirements rise.
That uncertainty is why r3 should still be read as a roadmap milestone. IBM has not announced a public availability date, pricing, reservation model or customer-access terms for r3. The Register described it as an upcoming processor rather than an available system. The planned 1,040-qubit machine is a 2027 target, not a delivered product, and nothing in the announcement shows fault tolerance.
The enterprise case lives in the workflow
IBM’s strongest strategic move may be outside the chip itself. Alongside r3, the company announced a more integrated IBM Quantum Platform that wraps quantum workflows with CPU, GPU, storage, error-mitigation, noise-learning and post-processing resources. That matters because enterprise users rarely buy a quantum processor in isolation. They buy time-to-result inside a broader computing stack.
This is also where IBM’s partner examples become more relevant than raw qubit totals. The company cites work with RIKEN in which scientists ran a workflow about five times faster and performed 100 times more computations than in the original study. It also cites work involving Cleveland Clinic and RIKEN that processed roughly 608 million samples with 33-times-faster automation. Those examples point to the practical bottleneck IBM is trying to remove: not just quantum execution, but the orchestration around it.
For research-heavy users in chemistry, materials, energy, pharmaceuticals, optimization and HPC operations, that integration could be the difference between a promising experiment and a usable service. E.ON’s presence among r2 users hints at grid and energy applications. RIKEN and Cleveland Clinic show where hybrid quantum-classical workflows might matter first: environments already comfortable with large-scale simulation, automation and repeated trial runs.
The catch is that most of the published gains are relative to earlier IBM processors or earlier workflow versions, not necessarily the best classical implementation of the same task. They are also vendor- or partner-reported results, not independent audits of commercial outcomes.
What buyers should ask next
For enterprise readers, the right response to Nighthawk r3 is not skepticism for its own sake, and not a victory lap over 520 qubits. It is a diligence checklist.
The first question is whether IBM can publish workload-level evidence that the announced 10,000 operations remain useful after error mitigation, not just achievable on paper. The second is whether the company can show logical-qubit performance, application-level error rates and reproducibility on representative workloads. The third is financial: what are the access terms, queue times and end-to-end costs once the quantum run, classical post-processing and storage are counted together?
Then comes the competitive test. A buyer should want to see the same workload compared across r2, r3 and the best available classical baseline, not just against older IBM hardware. If r3 can preserve accuracy, keep sample throughput high and cut the classical overhead surrounding quantum runs, IBM will have a stronger case that its platform is becoming economically useful. If not, the announcement will look more like a well-executed roadmap update than a change in enterprise adoption.
That makes Nighthawk r3 an important development even before it is in customers’ hands. IBM is no longer asking the market to judge quantum progress by qubit count alone. It is asking to be judged on modular scale, systems integration and workflow economics. That is a tougher test — and a more meaningful one.
 By
 By

 By